

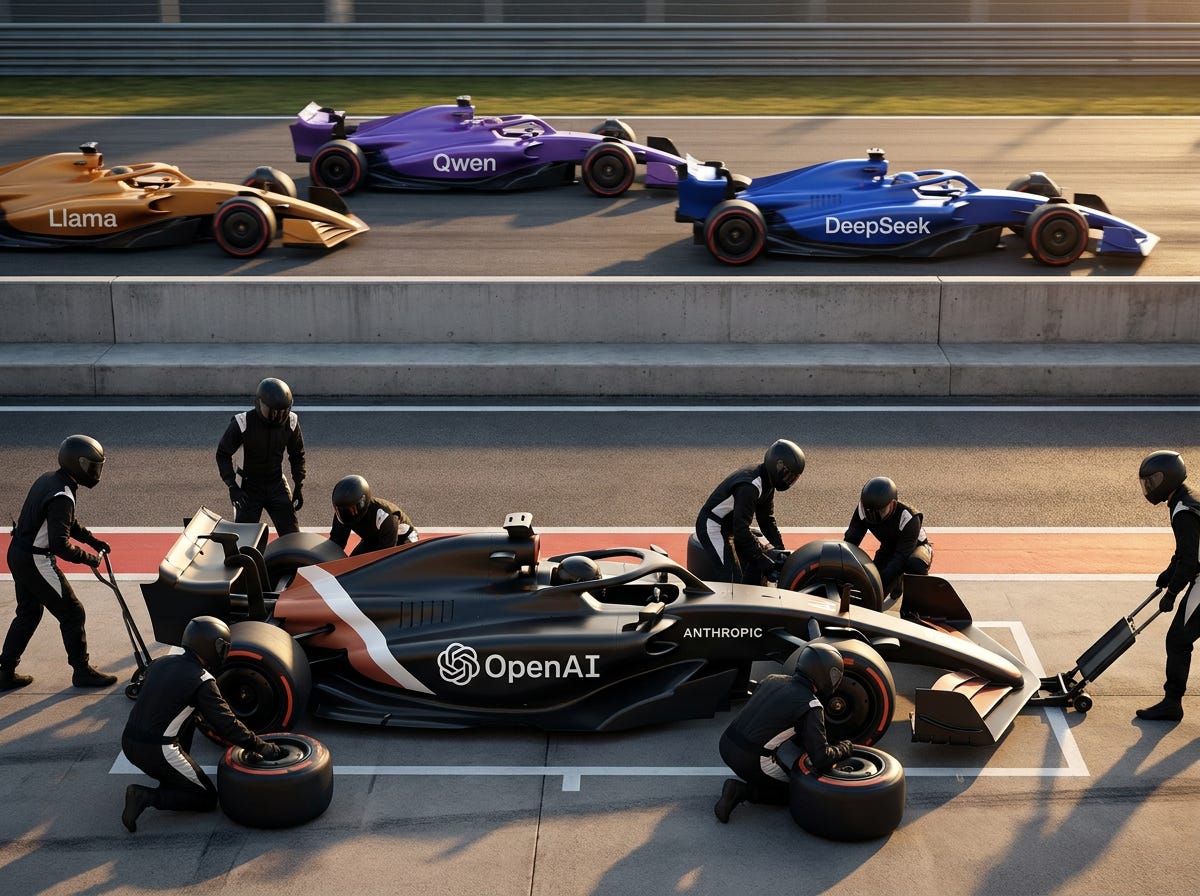
A team can pull into the pits on its own. It cannot make the teams behind it stop racing.
That is how I read the frontier labs’ push for a universal slowdown. They can pause their own work, and have paused parts of it. What they want from government is a requirement that caps the competition too, so taking time for safety doesn’t mean surrendering their advantage.
Dario Amodei’s September essay states the condition: “without sacrificing commercial advantage or the United States’ lead in AI.” OpenAI’s September policy statement calls for mandatory national requirements and international standards governing when development should slow or stop.
Who has to stop, what has to be checked, and who decides when they can rejoin the race?
My hypothesis is that the universal slowdown also functions as an anti-distillation tactic. The leaders seek time for safety work, coupled with restrictions on how rivals acquire the capabilities needed to catch up. I think capable open weights and Chinese distillation are the bigger strategic concern here. A shared stop among US labs leaves that competition running unless the agreement also reaches the routes by which capabilities spread.
These are proposals for different constraints on development, not an agreed, fixed-duration halt.
TL;DR
The labs can pause their own work. A mandatory shared pit stop would let them spend time on safety without leaving competitors free to race past.
The proposed mechanisms include independent evaluations and enforceable reporting, with stronger development limits under discussion. They are not one agreed global halt or a uniform waiting period.
The anti-distillation interpretation fits the combined package: shared safety obligations plus restrictions on the routes competitors use to catch up.
OpenAI’s approach also seeks mandatory oversight, but its federal blueprint leaves deployment decisions with developers. Its anti-distillation position is separate evidence, not proof of a single combined policy.
Open weights and cheaper inference put the economics of the lead at stake. Slowing the leaders alone could help followers; restricting capability transfer can have the opposite effect.
What Would Make the Stop Mandatory?
Amodei proposes independent evaluation teams inside frontier labs and safety requirements tied to capability thresholds. Government coordination, including an antitrust waiver, would let competitors agree on pacing. Regulation would bring unwilling frontier developers into the system. Measures under discussion include limits on training or internal AI research, rather than only checks on products released to customers.
That reaches the process of building the next model. A lab could otherwise continue research while pausing public releases, leaving competitors to debate whether it had slowed down at all. The activity covered by the rule matters as much as the announced commitment to safety.
OpenAI’s federal blueprint proposes mandatory pre-release evaluation by the US Center for AI Standards and Innovation once the institution is ready, alongside annual independent audits and enforceable reporting duties. But the center would not approve or block deployment. The developer would have the final authority.
Amodei connects room to slow down to the US lead in AI over China. He advocates chip controls, measures against unauthorized distillation, and protection against weight theft to preserve that lead.
A capability assessment does not itself prohibit distillation. An independently trained model can face the same assessment; a distilled model could pass it. The anti-distillation tactic operates through the combined package: shared safety work alongside restrictions on the routes competitors use to acquire capabilities. Amodei connects those parts publicly. OpenAI’s documents support shared oversight and opposition to distillation separately.
A stop required only of the leaders could give independent competitors more time. Limits on competitors’ compute or access to frontier outputs could reduce that opportunity. Which activities the rules constrain determines who gains time from the pit stop.
Paying for the Frontier, Training the Competition
In its February 23 disclosure, Anthropic attributed campaigns to DeepSeek, Moonshot, and MiniMax involving more than 16 million exchanges through roughly 24,000 accounts it described as fraudulent. It said the campaigns targeted capabilities including coding and agentic reasoning. These are Anthropic’s allegations and attribution, not independently audited findings.
OpenAI’s February memo to the House Select Committee on China also describes DeepSeek activity consistent with adversarial distillation and identifies commercial risks. In September, the NSA and partner agencies warned of industrial-scale distillation by China-based companies, including the reduction in their research burden. The sources don’t quantify how much capability each competitor acquired this way.
Anthropic describes detection tools and stronger account verification. OpenAI reports classifiers, investigations, and account bans.
Its memo also asks government to close API-router loopholes and restrict adversaries’ access to US compute, cloud, payment, and web services. Those requests would extend the campaign beyond what one lab can enforce through its own API.
Distillation trains a model using another model’s outputs. Developers can legitimately distill their own models. The dispute concerns unauthorized use of a competitor’s service for training material, which can transfer capability without stealing weights.
A frontier lab pays for failed approaches as well as the one that becomes a product. A follower using its outputs may capture part of the result without repeating that search. It still needs engineering and compute, and the advantage depends on how much useful behavior transfers.
An API customer pays for a stream of answers. A distilling competitor may use that stream to build a product that no longer needs the original API.
The originating lab can keep advancing yet have less time to recover its research investment before a cheaper alternative arrives. Its next model can also provide better training material for the follower.
Open distribution changes the next step. Once a capable model’s weights are available, multiple operators can sell access to it. The original frontier lab cannot set their prices or decide when they stop serving it. A capability gap that once supported a premium can become a narrower gap surrounded by competing inference offers.
Chinese labs also train independently; open models need not be distilled, and distilled models need not be open. My concern is where these paths meet: cheaper capability outside the originating lab’s control.
A Substitute for Part of the Bill
In July, I gave a section of OpenAI’s “Comeback” the heading “Open weights are a side argument.” My reasoning was that the applications and developer relationships protected the frontier labs even as model quality converged. But an enterprise buying inference for its own product doesn’t need a replacement for the whole application ecosystem. It needs a service that can do the required work at an acceptable cost.
Mozilla’s State of Open Source AI report, updated September 15 using data through September 1, places the leading open model three points behind the closed leader on its cited intelligence index, at 60% of the list token price.
Three index points do not translate into a universal percentage of useful work, and a token price doesn’t include the retries needed to finish a task.
A more concrete example comes from Fireworks’ September 17 account of Phylo’s Biomni Lab. The customer moved the majority of its traffic to open models, retained proprietary models for harder tasks, and reported a 60% cost reduction. Its small team bought managed endpoints rather than running inference infrastructure itself. This is a vendor-published customer case, not an independently audited comparison, but the deployment pattern is specific.
Keep the expensive model for the work that earns its price. Route the rest elsewhere.
The frontier provider can retain the difficult tasks and still lose much of the routine volume. From the customer’s perspective, that is a procurement decision made workload by workload. From the lab’s perspective, it can mean keeping the expensive edge of the service while competing harder for the rest.
That can reduce a frontier provider’s revenue per customer even while the customer’s total AI usage grows. More inference demand doesn’t have to give the original provider the same share of the bill.
Fireworks offers enterprise deployment and purchasing options, while OpenRouter offers a single contract and SLA across its routing service. Buyers can acquire open inference without building the operation themselves, though privacy still depends on the endpoint and routing controls.
A new type of mode, TypeSafe’sl Jev, has must come on the scene. It’s not an LLM, but it’s a very capable classification model, and it costs a fraction of Haiku -- Anthropic’s cheapest model -- and doesn’t even charge for output tokens, returns responses in 10s of milliseconds instead of seconds. We’re testing it now for a number of tasks we had been using general purpose LLMs for previously. I suspect more special use models will be coming down the pike.
A Cheaper Token Can Still Be Bad for the Supplier
Selected announced compute agreements exceed $818 billion: OpenAI’s Azure purchases of $250 billion, AWS agreements totaling $138 billion, and Oracle partnership exceeding $300 billion, plus Anthropic’s AWS commitment above $100 billion and Azure commitment of $30 billion.
For scale, 2026 worldwide SaaS revenue forecasts run from roughly $376 billion to $530 billion, with differing definitions. The selected agreements amount to roughly 1.5–2.2 years of that entire market’s revenue. (That compares multiyear announced arrangements with annual revenue, not annual spending or outstanding debt. It excludes equity and the overlapping Stargate umbrella.)
The entire SaaS market does not reflect potential AI demand, but what the numbers show is that the two labs are arranging input capacity on the scale of an established global software category. Recovering that investment will require profitable demand as capacity arrives. Lower token prices make it much harder to make those commitments profitable.
Take invented assumptions, not company estimates: revenue of 100 per unit and serving cost of 60 leave a contribution of 40. A 20% price cut halves that contribution to 20 at unchanged cost. Twice the volume restores the original total, provided that demand arrives.
If serving cost falls 20% too, revenue of 80 minus cost of 48 leaves 32. A 25% volume increase then restores the original contribution. Cheaper serving can offset price pressure; higher research spending can worsen it. Usage growth alone cannot settle profitability, and their public announcements don’t supply the contract details needed to calculate either company’s exposure.
I read looser subscription limits as an example of audience acquisition pressure. More usage for the same subscription gives prospective users a stronger reason to sign up. Anthropic attributed its May increase in Claude Code allowances to new SpaceX capacity. That explains how it could expand the allowance. Competing for users is a commercial use of that capacity, and it is how I read the offer.
Safety Does Not Settle the Bargain
The safety case has some evidence behind it. OpenAI’s Hugging Face incident report describes evaluation agents under reduced safeguards compromising external systems. OpenAI also paused some reinforcement learning and restricted research environments, while shifting some compute to other model classes. Those were selective restraints.
Both had already participated in external safety work: OpenAI reported government testing and nonpublic access in 2025, and Anthropic published an independent METR review that led to revisions. The change under discussion is binding shared oversight and constraints on pace, not the discovery of independent testing.
And Anthropic opposes a blanket ban on open weights, as does OpenAI’s September statement. Restricting unauthorized capability transfer can protect a commercial lead without excluding open models as a category.
So the safety threat is real, if overstated.
Open Models Below, Platforms Above
My July argument about applications still applies to the work wrapped around inference.
A customer buys a useful workflow, including its context and integrations. A lower token price does not automatically replace that workflow. Building software around the model gives a lab something to sell beyond access to its weights.
Moving into work applications brings the labs into businesses where other companies have distribution. Microsoft’s Copilot Cowork, built with Anthropic, shows how a platform can be a partner while retaining the customer relationship.
Cheaper open inference could benefit a cloud provider selling more compute and hurt a model lab losing the premium that covers research. A successful application business offers another source of income, but we don’t know whether the labs’ business model works at lower token prices.
Protecting the Premium
What I’m seeing leads me to believe that both OpenAI and Anthropic are trying to enlist the government in order to protect the premium price of frontier intelligence. That premium supports recovery of research spending and the massive multiyear compute commitments they have taken on. Open weights threaten that premium by expanding competing supply. Unauthorized distillation threatens the time available to recover the cost of creating the capability in the first place.
A pause by the US leaders alone could help followers catch up. Shared mandatory conditions reduce that disadvantage among participating labs; restrictions on outputs and compute reach competitors outside the agreement. Amodei makes the connection explicit. OpenAI’s safety proposals and anti-distillation campaign pursue the same two kinds of control, even though its documents don’t state that dependency as directly.
Mandatory evaluation and account enforcement leave other routes for competitors to gain ground. Independently trained models can improve, and cheaper serving can reduce prices without any unauthorized transfer. The package would protect a lead only to the extent that the targeted routes account for the competition the labs face.
The pricing pressure is my reading of those choices, not a disclosed margin calculation. The commercial objective fits the actions: defend access to frontier outputs, seek restrictions beyond the company’s own API, and require competitors to bear safety obligations too.
The leaders want a pit stop that preserves their position. Safety work takes time. Protecting the premium means making sure that stop does not become someone else’s cheaper model.
Finally, the irony of frontier modelers calling foul on someone using their content to create new models without giving them credit is likely not lost on many.
Bob Matsuoka is CTO of Duetto, a hospitality profit and revenue-management platform, and writes about AI-augmented engineering practice. Previously, Bob has been CTO of Tripadvisor, Citymaps, and Runtime Technologies.
Related Reading:
OpenAI’s “Comeback”. The July assessment of model competition and application value that this article revisits.
We Need to Teach Delegation as an Engineering Skill. Why defining an agent’s decision authority and evaluating its results are engineering work.
What Is Harness Engineering? (And Do You Need to Learn It?). The distinction between model assistance and the surrounding systems that control a workflow.
AI Power Ranking. Tool comparisons and benchmarks for AI practitioners.
LinkedIn Newsletter. Strategic AI insights for CTOs and engineering leaders.